Add TOPKHOJ as a Preferred Source on Google
Google DeepMind has expanded its generative audio portfolio with the debut of Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS. Described by Google as its most expressive text-to-speech systems to date, the dual-model family introduces voice generation capabilities designed to bridge the gap between flat speech synthesis and natural, context-aware human delivery.
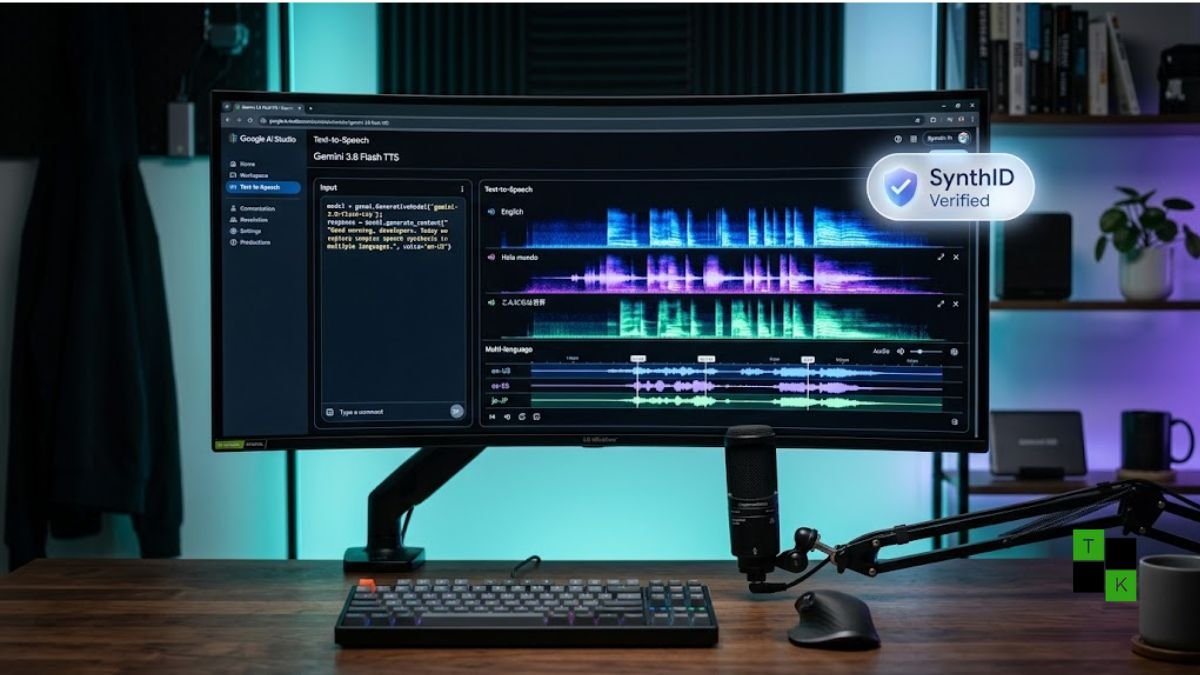
The models support over 100 languages and provide access to a library of more than 2,000 pre-crafted, production-ready voices. In addition, developers can design custom synthetic voices directly through natural-language prompts or replicate vocal profiles using short reference audio samples. Both releases are available via the Gemini API and Google AI Studio, backed by embedded SynthID audio watermarks and competitive volume pricing starting around $23 per million characters.
Flash TTS vs. Flash-Lite TTS: Creative Control vs. High-Volume Scale
Google has structured the release into two specialized tiers to address distinct developer needs:
- Gemini 3.8 Flash TTS: Built for high-fidelity creative applications such as interactive video game dialogue, dynamic audiobooks, and narrative podcasts. The flagship model provides granular direction over tone, emotional intensity, inflection, pacing, and multi-speaker screenplays while keeping voice characteristics consistent across long passages.
- Gemini 3.8 Flash-Lite TTS: Optimized for low-latency throughput and large-scale deployments, such as high-volume multi-lingual video dubbing, live voice agent cascades, and automated customer service routing. It balances natural expressiveness with lower compute requirements, making it ideal for high-traffic environments.
Gemini 3.8 TTS Model Architecture & Features
| Capability / Metric | Gemini 3.8 Flash TTS | Gemini 3.8 Flash-Lite TTS |
| Primary Focus | Expressive Creative Direction & Screenplays | High-Volume Scale, Dubbing & Fast Agents |
| Language Support | 100+ Global Languages & Accents | 100+ Global Languages & Accents |
| Pre-Built Voice Library | 2,000+ Production-Ready Voices | 2,000+ Production-Ready Voices |
| Custom Voice Creation | Prompt-Based Voice Design & Audio Replication | Voice Replication from Audio Clips |
| Multi-Speaker Support | Native Two-Speaker Script Execution | Single & Multi-Voice Agent Workflows |
| Safety Watermarking | Embedded SynthID Audio Watermarking | Embedded SynthID Audio Watermarking |
| Quality Benchmark | #1 on Hume AI Overall Quality Index | #2 on Hume AI Overall Quality Index |
| Estimated Pricing | ~$33 per Million Characters | ~$23 per Million Characters |
| API Availability | Google AI Studio & Gemini API | Google AI Studio & Gemini API |
Natural Language Voice Design and Voice Replication
A major innovation in the 3.8 architecture is generative voice design. Rather than relying exclusively on fixed voice actors, developers can describe an aesthetic identity in natural language. Prompts such as “a raspy, weathered narrator with a calm cadence” or “an energetic, upbeat presenter with an Australian accent” generate consistent vocal identities from scratch.
For localized branding and dubbing, the models offer voice replication. Using reference audio clips as short as 30 seconds, the engine can match the timbre, cadence, and vocal quirks of an original speaker, allowing content to be dubbed across multiple languages while preserving the speaker’s vocal identity.
Hume AI Benchmarks and Safety with SynthID
On third-party evaluations, the new models set strong performance markers:
- Hume AI Quality Index: Gemini 3.8 Flash TTS and Flash-Lite TTS achieved the #1 and #2 spots on Hume AI’s Overall Quality Index, showing significant improvements in long-form stability and dual-speaker screenplay execution over Gemini 3.1 Flash TTS.
- Voice Design Benchmark: Gemini 3.8 Flash TTS earned the top overall position with a score of 71.4 on Hume AI’s Voice Design Benchmark, outpacing competing models like ElevenLabs Voice Design v3 in accent accuracy and emotional modeling.
- SynthID Watermarking: To address concerns around synthetic voice misuse and unauthorized cloning, every audio file produced by the Gemini 3.8 TTS pipeline contains an imperceptible SynthID watermark. The watermark survives standard compression, downsampling, and background noise manipulation, enabling downstream systems to verify AI origin.
Early Adopters and Developer Pricing
Google confirmed that partners including HeyGen, Figma Weave, Kuku FM, and Linguana have already integrated Gemini 3.8 TTS into automated dubbing pipelines, storytelling platforms, and real-time voice agents.
Both models are live for experimentation inside Google AI Studio and can be deployed in production through the Gemini API. With pricing set between $23 and $33 per million characters, DeepMind is positioning Gemini 3.8 TTS as a cost-effective alternative to specialized voice-generation providers, giving developers a direct path to build multimodal applications inside the Google Cloud ecosystem.
🚨 Stay Updated with TopKhoj! 🚨
Get the latest tech news, deals, and exclusive offers first!
📰 Visit News Section📲 Join our Telegram Channel for real-time updates and best deals!
🔗 Join Telegram Now💡 Stay informed and never miss a great deal with TopKhoj!
⚠️ Disclaimer: Any link provided in the article related to a product or service will redirect you to our affiliate partner(s)' website, which are affiliate links. This means that if you make a purchase through these links, we may earn a commission at no extra cost to you. This commission helps support our blog and our work.
🔔 All prices mentioned above are subject to change based on current offers and availability on e-commerce platforms. Please check the latest price and product details on the product page before making a purchase.